

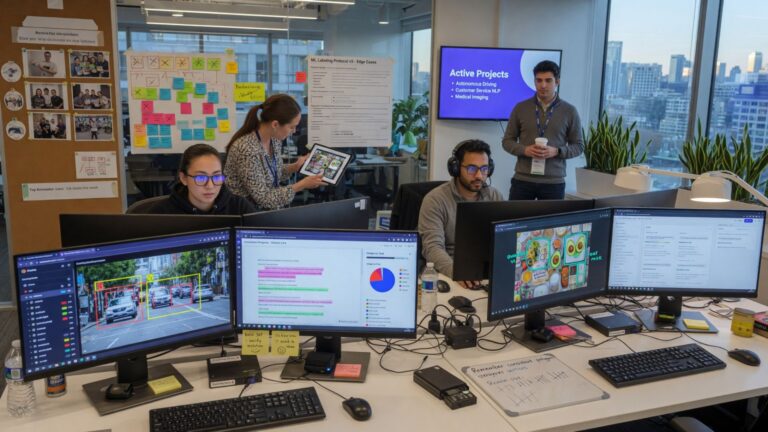
Artificial intelligence relies entirely on the quality of the information it consumes. Therefore, the foundation of any successful machine learning project begins with how you prepare your datasets. When you Label Your Data correctly, you provide the contextual framework algorithms need to recognize patterns and make accurate predictions. Furthermore, precise data annotation bridges the gap between raw information and actionable AI intelligence. Consequently, organizations must treat this process as a critical strategic investment rather than a simple administrative task.
The Importance When You Label Your Data
High-quality annotations directly dictate model performance. If you feed an algorithm poorly categorized information, the resulting AI will make poor decisions. Therefore, accuracy during the annotation phase is non-negotiable. A model cannot learn beyond the boundaries of its training data. Furthermore, poor labeling introduces noise into the dataset, confusing the algorithm during the training phase. Consequently, teams spend massive amounts of time and money debugging models that simply suffered from bad input data.
Training AI Models with High-Quality Annotations
Algorithms learn by example. For instance, a computer vision model identifying pedestrians needs thousands of images with bounding boxes drawn perfectly around humans. If those boxes are slightly off, the model learns the wrong visual cues. Therefore, spending extra time to ensure precise annotations saves countless hours of debugging later. Furthermore, high-quality training data reduces model bias, leading to fairer and more reliable AI deployments. Thus, the rigor applied to annotation directly correlates with the commercial viability of the final AI product.
Methods to Label Your Data Efficiently
Organizations must choose the right annotation methodology based on their project scope and budget. Generally, teams choose between manual, automated, or hybrid approaches. Each method carries distinct advantages and limitations. Therefore, understanding the nuances of each approach ensures teams select the most efficient path forward. Evaluating the complexity of the data helps determine which method fits best.
Manual, Automated, and Semi-Automated Approaches
Manual annotation involves human labelers tagging data point by point. This method offers the highest accuracy for complex tasks like sentiment analysis or nuanced image segmentation. However, manual annotation is time-consuming and expensive. Conversely, automated annotation uses pre-trained AI models to tag new data quickly. While fast, automated methods lack the nuance of human judgment and often require manual correction. Therefore, many teams adopt semi-automated approaches. In this setup, an AI model pre-labels the data, and human reviewers correct any errors. Consequently, this hybrid method maximizes both speed and precision, making it ideal for large-scale enterprise projects.
Choosing the Right Tools to Label Your Data
The software platform you select heavily impacts annotation speed and quality. Therefore, engineering teams must evaluate platforms based on their specific data types, whether text, image, audio, or video. A tool designed for natural language processing will not handle bounding box tasks for autonomous vehicles effectively. Thus, selecting specialized software ensures the annotation team works efficiently without fighting unintuitive interfaces.
Features of Top Data Annotation Platforms
A robust annotation tool must offer customizable interfaces for different labeling types, such as polygons, bounding boxes, or named entity recognition. Furthermore, it should include quality assurance features like consensus scoring, where multiple labelers annotate the same item to check for agreement. Additionally, API integrations allow seamless data transfer between the annotation tool and the machine learning pipeline. Therefore, choosing a platform with strong integration capabilities streamlines the entire development lifecycle. The best platforms also feature automated quality controls that flag inconsistent labels before they reach the training phase.
Industry Use Cases When You Label Your Data
Different industries face unique annotation challenges based on their operational requirements. A one-size-fits-all approach rarely works across different sectors. Therefore, annotation strategies must adapt to specific industry demands, regulatory environments, and data sensitivities. Understanding these use cases helps organizations benchmark their own data preparation workflows against industry standards.
Healthcare, Automotive, and Retail Applications
In healthcare, medical professionals annotate X-rays and MRI scans to train diagnostic AI. This requires highly specialized knowledge, so doctors themselves must oversee the annotation process. In the automotive sector, self-driving cars rely on annotated video feeds to identify traffic lights, pedestrians, and road signs. Meanwhile, retail companies annotate customer reviews to train sentiment analysis models that track brand perception. Consequently, the approach to annotation must shift dramatically depending on the specific industry requirements. The tolerance for error in medical imaging is vastly lower than in retail sentiment analysis, dictating a much stricter quality assurance process.
Quality Control When You Label Your Data
Even the best human labelers make mistakes. Therefore, rigorous quality control mechanisms must govern the annotation pipeline to ensure the final dataset is reliable. Without quality control, machine learning models train on erroneous data, leading to unpredictable outputs in production. Thus, implementing multi-layered review processes safeguards the integrity of the entire machine learning project.
Ensuring Accuracy and Consistency
Teams must establish clear annotation guidelines before the project begins. These guidelines serve as a rulebook for edge cases and ambiguous data. Furthermore, project managers should implement honeypot tasks. These are pre-labeled tasks secretly inserted into the workflow to test if labelers are paying attention. If a labeler consistently fails honeypot tasks, they require retraining. Consequently, active quality monitoring prevents dataset corruption and ensures high model accuracy. Regular feedback loops between labelers and data scientists also ensure everyone aligns on the evolving definition of a correct label.
Overcoming Challenges to Label Your Data
Scaling an annotation project presents significant operational hurdles. As datasets grow from thousands to millions of items, maintaining quality and security becomes increasingly difficult. Furthermore, finding enough qualified human labelers poses a massive logistical challenge for rapidly growing tech companies. Therefore, anticipating these bottlenecks helps project managers plan accordingly.
Managing Scale and Data Security
Large-scale projects often require crowdsourcing labor or outsourcing to specialized data labeling services. While this solves the manpower issue, it introduces security risks. Sensitive data, such as medical records or proprietary technology blueprints, must remain protected. Therefore, organizations must use secure annotation environments with strict access controls and data masking techniques. Furthermore, managing a remote workforce requires robust project management software to track progress and productivity. Consequently, balancing scale with strict security protocols remains a critical operational challenge. Companies must sign comprehensive non-disclosure agreements with third-party labeling vendors to protect intellectual property.
Future Trends in How We Label Your Data
The annotation industry evolves rapidly alongside advancements in artificial intelligence. New technologies are making the preparation of training data faster and more cost-effective. Therefore, engineering teams must stay updated on these trends to maintain competitive advantages in AI development. The future points heavily toward reducing human involvement in routine annotation tasks.
AI-Assisted Annotation and Synthetic Data
AI-assisted annotation is becoming the industry standard. Modern platforms use predictive algorithms to auto-suggest labels, which human workers simply accept or refine. Furthermore, generating synthetic data is gaining massive traction. Engineers create artificial datasets using 3D rendering engines, automatically generating perfect labels alongside the data. For example, autonomous vehicle companies use synthetic weather conditions to train their cars without waiting for real blizzards. Therefore, synthetic generation drastically reduces the need for manual human annotation in specific use cases. This shift allows data scientists to focus on edge cases while AI handles standard labeling tasks.
FAQs
1. What does it mean to Label Your Data?
It means adding meaningful tags or metadata to raw datasets so machine learning algorithms can recognize patterns and learn to make predictions.
2. Why is data labeling important for AI?
Algorithms require labeled examples to understand what they are looking at; without accurate labels, AI models cannot learn effectively or make correct decisions.
3. What is the difference between manual and automated annotation?
Manual annotation relies entirely on human input for high accuracy, while automated annotation uses pre-trained AI to label data quickly but with less nuance.
4. How do you ensure quality when you Label Your Data?
Teams ensure quality by using consensus scoring, honeypot tasks, clear annotation guidelines, and continuous feedback loops between labelers and data scientists.
5. Can AI label its own training data?
Yes, AI-assisted annotation allows models to pre-label data, but human oversight remains necessary to correct errors and handle complex edge cases.
6. What is synthetic data generation?
It is the process of creating artificial datasets using computer algorithms, which provides perfectly labeled data without the need for manual human annotation.
Conclusion
The success of any artificial intelligence initiative hinges directly on the quality of its training inputs. When you Label Your Data with precision and rigorous oversight, you establish a reliable foundation for machine learning models to thrive. Furthermore, adopting the right mix of manual and automated annotation methods ensures teams scale efficiently without sacrificing accuracy. As AI-assisted tools and synthetic data generation continue to evolve, the annotation process will become faster and more sophisticated. However, human oversight will remain critical for handling nuanced edge cases and ensuring ethical AI deployment. Ultimately, prioritizing high-quality data annotation transforms raw information into a powerful competitive advantage, driving accurate and dependable machine learning outcomes.


